An AI agent and a chatbot get discussed as if they’re the same thing, and on AWS specifically, that confusion costs teams real engineering time. A chatbot answers a question. An agent decides what to do, calls a tool to do it, checks the result, and decides what to do next and building that reliably inside an enterprise AWS environment is a genuinely different engineering problem than calling a model API from a Lambda function. That distinction shapes nearly every decision covered in this guide.
This guide is written for teams that have already decided AWS is their platform and want a real architecture answer for enterprise AI agents with AWS Bedrock -not a marketing tour of Bedrock’s feature list, and not a basic tutorial that stops before the parts that matter at enterprise scale: identity and access boundaries, multi-agent governance, and what this actually costs once real employees or customers are using it daily.
If you haven’t yet decided between a foundation model API, fine-tuning, or custom training as your underlying AI approach, our broader guide to how to build an AI-powered app covers that decision first. This guide assumes you’re building on foundation models via API -Bedrock’s core offering -and focuses specifically on the agent layer on top of that: orchestration, tool use, and enterprise governance, which is the layer most existing Bedrock content treats too lightly.
What Is an AI Agent, and What Does Bedrock Actually Provide for Building One?
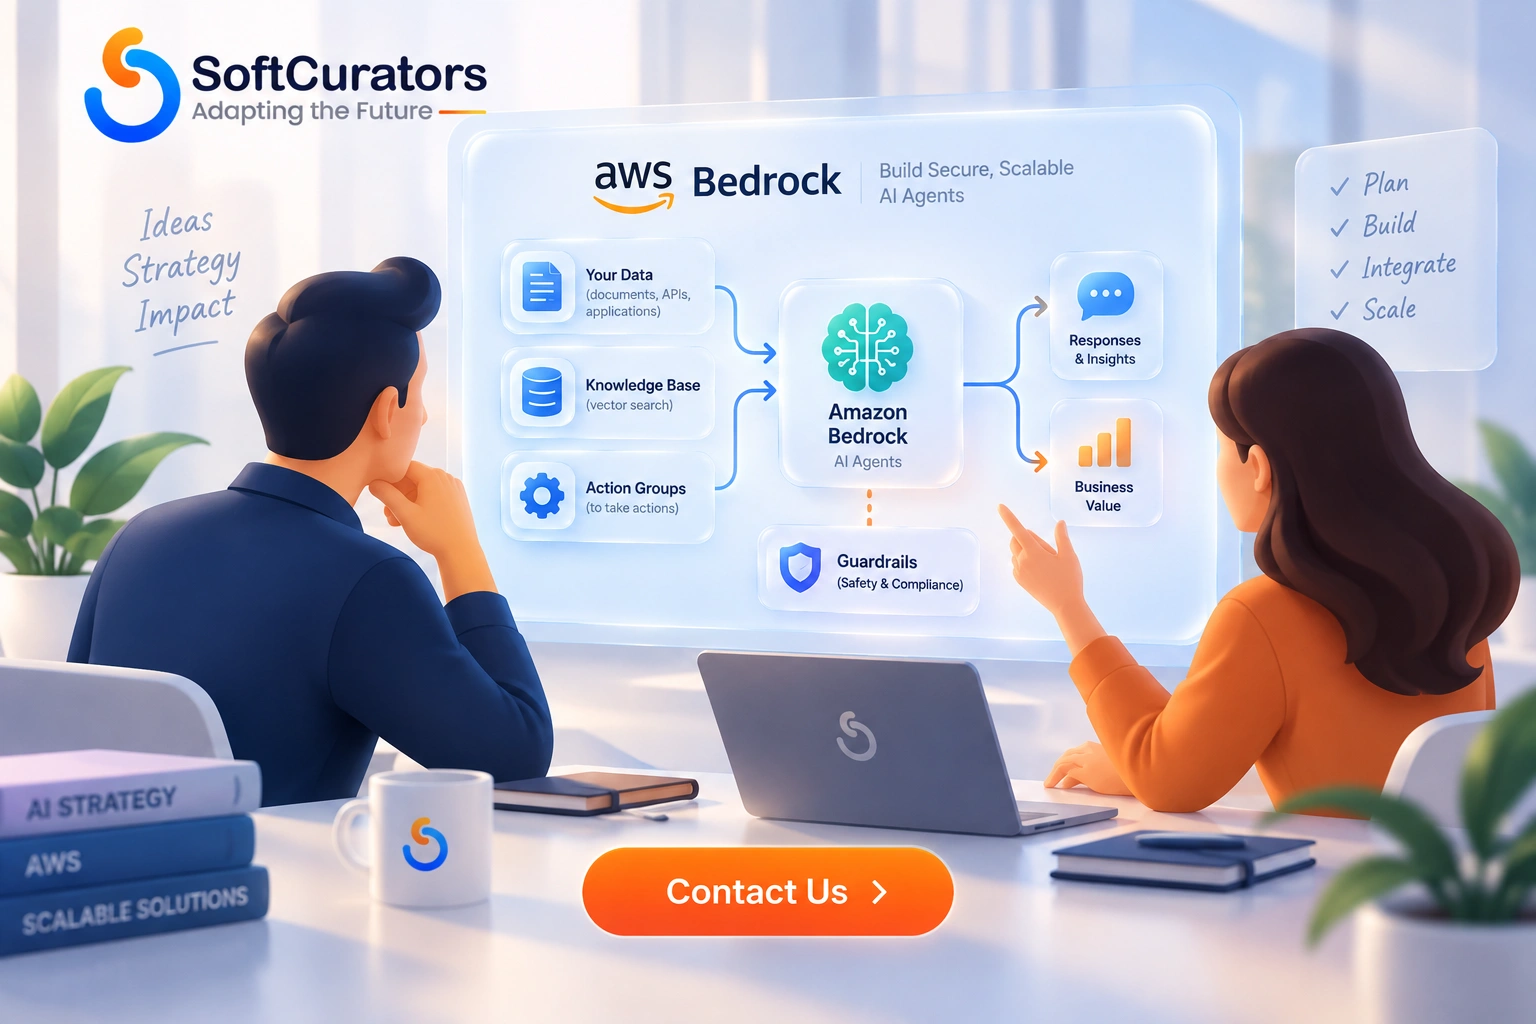
An AI agent is a system where a model doesn’t just generate a single response -it reasons about which action to take, invokes a tool or function to take it, evaluates the result, and decides on a next step, potentially across multiple turns, to complete a task rather than answer one question. AWS Bedrock provides four managed building blocks that together let you build this without assembling the orchestration logic entirely from scratch.
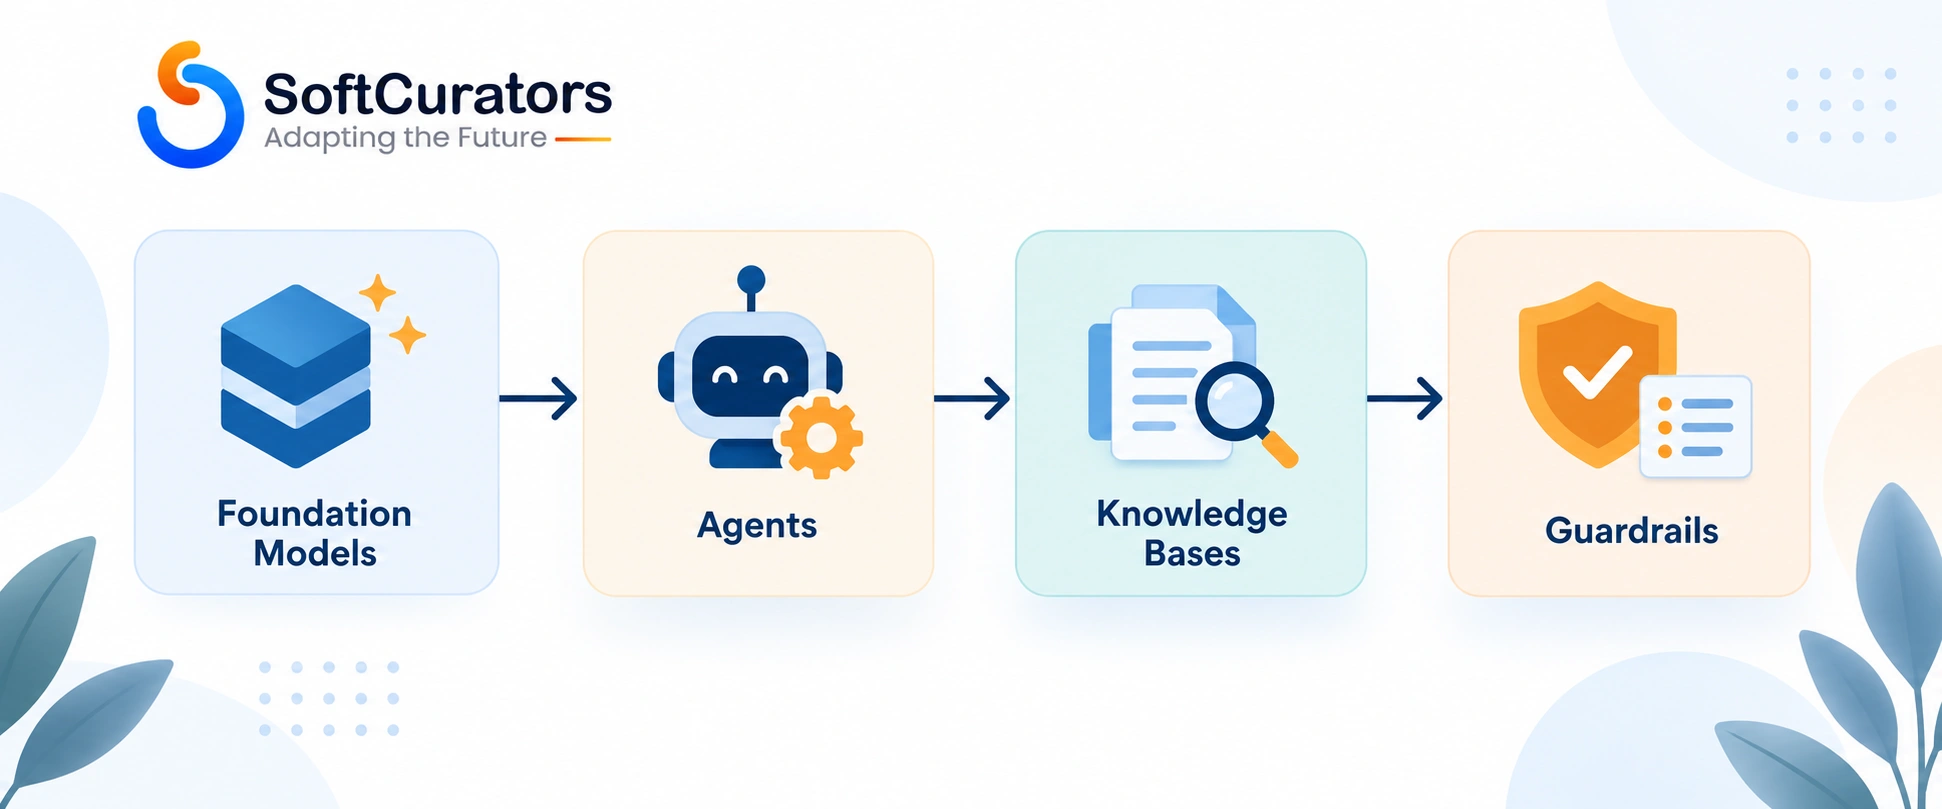
The four core building blocks are:
- Foundation model access -API access to models from multiple providers through a single AWS-managed interface, rather than integrating each provider separately.
- Agents for Bedrock -the managed orchestration layer that handles reasoning, tool selection, and multi-step execution.
- Knowledge Bases -managed retrieval-augmented generation (RAG), connecting your agent to your own enterprise data.
- Guardrails -configurable content filtering and safety controls applied consistently across your agents.
Reviewing AWS’s official Bedrock documentation directly is worth doing before any architecture decision, since AWS updates model availability and feature capability often enough that a summary written today can be stale within months -this guide focuses on the architecture reasoning that stays stable across those updates, not a feature inventory that won’t. Treat the reasoning here as the durable part, and the specific configuration details as something to confirm fresh each time you build.
Business Insight:
The value of building on Bedrock specifically, rather than assembling equivalent pieces from open-source agent frameworks on raw EC2 or Lambda, isn’t the AI capability itself -it’s that IAM, logging, and access control are already integrated with the rest of your AWS environment. For a team already running production workloads on AWS, that integration is worth more than the marginal flexibility a fully custom stack would offer, in most cases we’d actually recommend. Weigh that trade-off honestly against your own team’s priorities before assuming it applies automatically to your situation.
Why Build Agents on Bedrock Specifically, Rather Than a Model API Directly?
If you’re already committed to AWS, the honest comparison isn’t “Bedrock versus nothing” -it’s Bedrock versus calling a foundation model API directly and writing your own orchestration, security, and retrieval layers around it. Here’s our actual reasoning for defaulting to Bedrock in that comparison.
You Inherit IAM Instead of Rebuilding Equivalent Access Control
Bedrock agents and knowledge bases integrate with AWS Identity and Access Management (IAM), meaning your existing access policies, roles, and audit trails extend to your agent’s permissions rather than requiring a parallel security system you build and maintain yourself. Building the equivalent access control from scratch around a raw model API call is real, ongoing engineering work that Bedrock gives you by default.
You Get Multi-Provider Model Access Without Multiple Integrations
Bedrock provides access to models from multiple providers through one consistent API, which matters if you want to compare or switch between models without rebuilding your integration layer for each provider separately -a genuine, non-trivial engineering saving if you expect to evaluate more than one model over your agent’s lifetime.
Where Bedrock Isn’t the Right Answer
If your organization isn’t already running meaningfully on AWS, adopting Bedrock specifically to build one agent is usually the wrong sequencing -you’d be taking on a cloud platform decision to solve an AI architecture question, and that’s a much larger commitment than the agent itself justifies. In that case, a foundation model provider’s API directly, on whatever infrastructure you already run, is the more proportionate starting point.
Common Mistake: Choosing Bedrock because it’s the AWS-native option without checking whether your organization’s actual AWS usage justifies the platform lock-in. Bedrock’s value case depends on you already being invested in AWS’s ecosystem -it’s not a universal default independent of that context.
Agents for Bedrock: How the Managed Orchestration Layer Actually Works
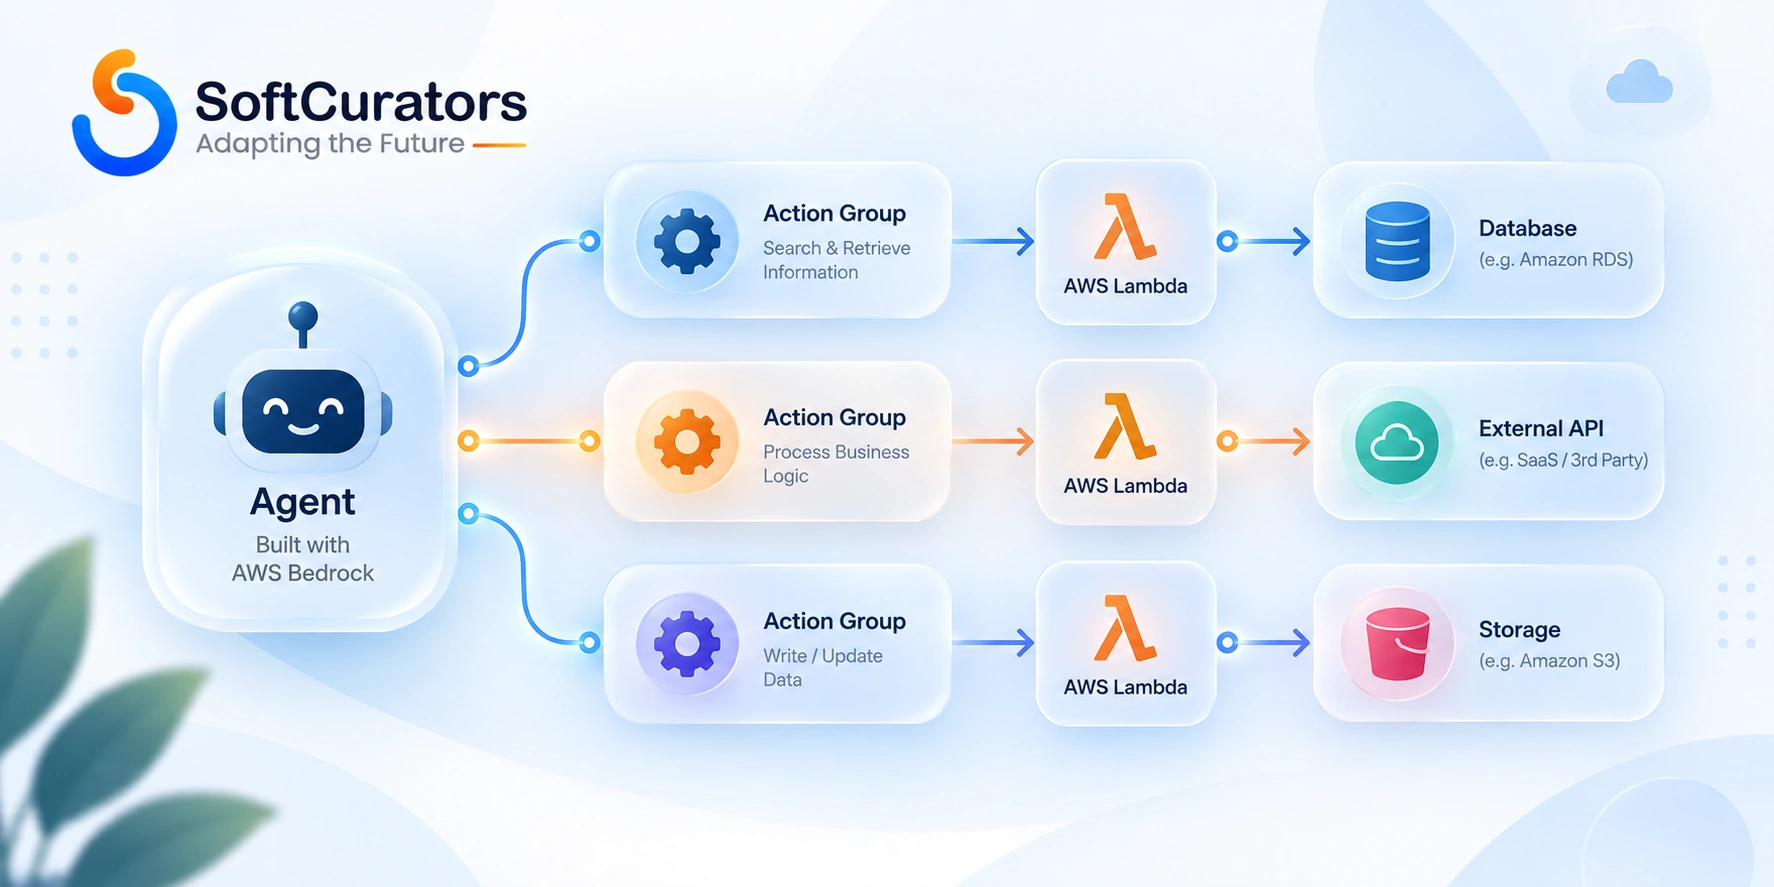
Agents for Bedrock handles the reasoning loop -interpreting a user’s request, deciding which action to take, calling it, and evaluating the result -through a structure built around action groups and, where needed, knowledge base integration, without you writing the orchestration logic that decides what happens next at each step.
Action Groups: Connecting Your Agent to Real Systems
An action group defines a set of functions your agent can call, each backed by an AWS Lambda function you write, with a schema describing what the function does and what parameters it needs. When the agent decides a task requires calling an internal API, checking a database, or triggering a workflow, it selects the matching action group function, and Bedrock handles passing it the right parameters based on the conversation context.
Why This Matters More Than It Sounds Like It Should
Technical Note: The quality of your action group’s function description directly determines how reliably the agent selects the right tool. A vague or ambiguous description leads to the agent calling the wrong function or failing to call one it should have -this is prompt engineering applied to tool definitions, and it deserves the same iterative testing discipline as any other prompt in your system, not a one-time write-and-forget description.
Reviewing AWS’s documentation on Agents for Bedrock directly is worth doing when you actually start building, since the specific configuration options and supported patterns are updated more frequently than a summary article can track reliably.
Knowledge Bases and RAG on Bedrock: Grounding Your Agent in Enterprise Data
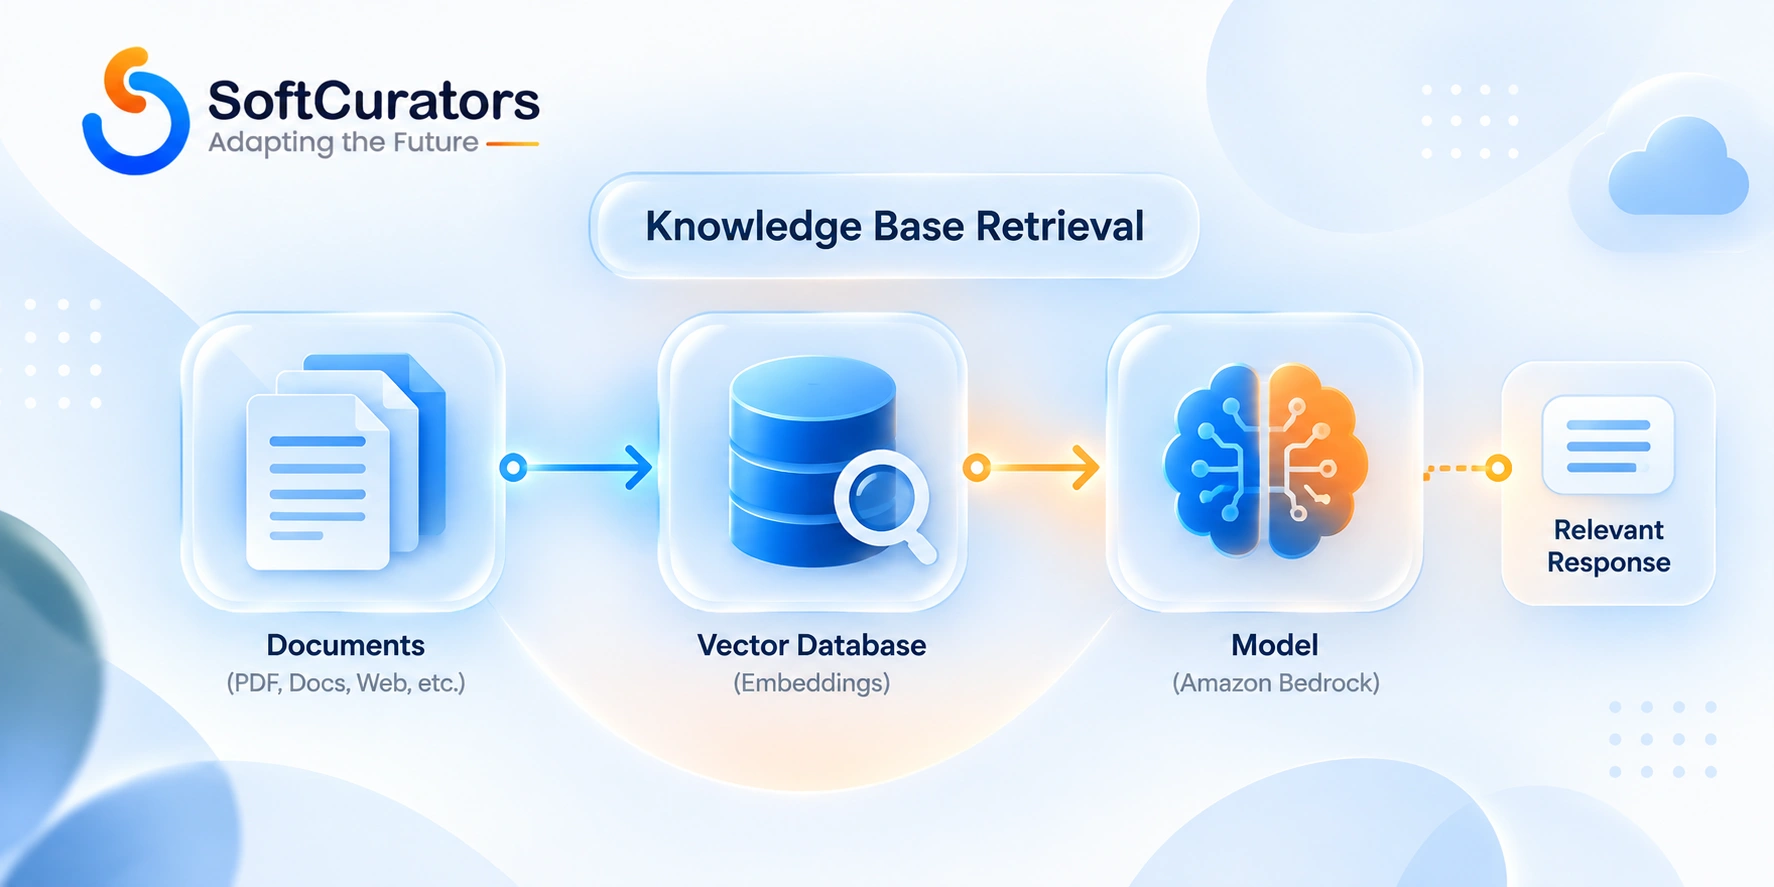
A foundation model knows general language and broad public knowledge. It doesn’t know your internal documentation, your product catalog, or your customer history. Bedrock Knowledge Bases handle the retrieval-augmented generation pattern -pulling relevant information from your own data at query time -as a managed service rather than infrastructure you build yourself.
How It Actually Works Under the Hood
A Knowledge Base ingests your source documents, splits them into manageable chunks, converts those chunks into vector embeddings, and stores them in a vector store -commonly Amazon OpenSearch Service or Amazon Aurora with vector support -so that at query time, the system can retrieve the most relevant chunks and include them in what’s sent to the model. Reviewing AWS’s documentation on Bedrock Knowledge Bases directly covers the current supported data sources and vector store options in more depth than a summary can capture reliably.
Data Sync Frequency Is a Real Design Decision
Business Perspective: A Knowledge Base only reflects your source data as of its last sync, and how often you sync is a genuine trade-off between data freshness and both cost and operational overhead -a knowledge base syncing hourly against rapidly changing data costs more to maintain than one syncing daily against slower-changing reference material. Match the sync frequency to how often the underlying data actually changes, not to a default setting, and revisit that choice periodically as your data’s rate of change evolves.
Our AI-powered DataOps guide and DataOps vs. DevOps vs. MLOps comparison both cover the broader data pipeline discipline a Knowledge Base depends on -a Knowledge Base is only as reliable as the data pipeline feeding it, the same way any AI feature is bounded by its underlying data quality.
How Do Bedrock Agents Handle Multi-Turn Conversations and Memory?
An enterprise agent rarely resolves a task in a single exchange -a user asks a follow-up, corrects an earlier statement, or picks up a conversation after a pause. How an agent handles that context directly affects whether it feels coherent or repeatedly asks the user to restate information they’ve already provided.
Session State Within a Single Conversation
Bedrock Agents maintain conversation state within a session automatically, tracking prior turns so the agent can reference earlier context when reasoning about a new request. This session-level memory is what lets a user say “actually, change that to next Tuesday” without repeating the entire original request.
Why Session Length and Timeout Design Matters
Business Perspective: A session that expires too aggressively frustrates users who pause mid-task and return to find the agent has forgotten the context; a session that never expires risks holding stale or sensitive context longer than necessary. Set session timeout based on your actual task’s realistic completion window, not a default value, and treat this as a deliberate design decision rather than an afterthought.
What Session Memory Doesn’t Cover
Technical Note: Session memory is scoped to a single conversation, not to a user’s history across separate sessions. If your use case needs an agent to remember a user’s preferences or history across multiple, separate interactions, that requires persisting relevant context to your own data store and retrieving it -commonly through the same Knowledge Base or a dedicated action group -rather than assuming Bedrock’s session handling covers it automatically.
How Do You Deploy and Version Agents Safely From Development to Production?
An agent that works well in testing needs a controlled path to production, the same way any software does -but agent behavior is harder to fully predict in advance than conventional code, which makes a careful deployment process more important, not less.
Aliases Let You Separate Testing From Live Traffic
Bedrock supports creating multiple versions of an agent and pointing different aliases -effectively named environments -at specific versions, letting you test a new configuration against a draft alias while production traffic continues hitting a stable, known-good version. This is the agent equivalent of a staging environment, and skipping it means testing changes directly against real users.
Roll Out Gradually, Not All at Once
Common Mistake: Pointing all production traffic at a new agent version immediately after it passes your evaluation set. An evaluation set, however thorough, can’t cover every real input your actual users will send -a gradual rollout, monitoring tool-selection accuracy and escalation rates as traffic increases, catches problems an evaluation set alone won’t surface.
Operational Perspective: Keep your evaluation set updated with real production examples that surfaced problems, not just the original test cases you started with. An evaluation set that never grows past its initial version stops reflecting your agent’s actual failure modes as usage patterns evolve.
The Central Decision: Managed Bedrock Agents or Custom Orchestration on Bedrock Models?
Here’s the actual architecture decision most Bedrock content skips: you can use Agents for Bedrock’s managed orchestration, or you can call Bedrock’s foundation models directly and write your own orchestration logic -deciding what to do at each step yourself, in your own application code. These are not equivalent effort, and we have a clear default.
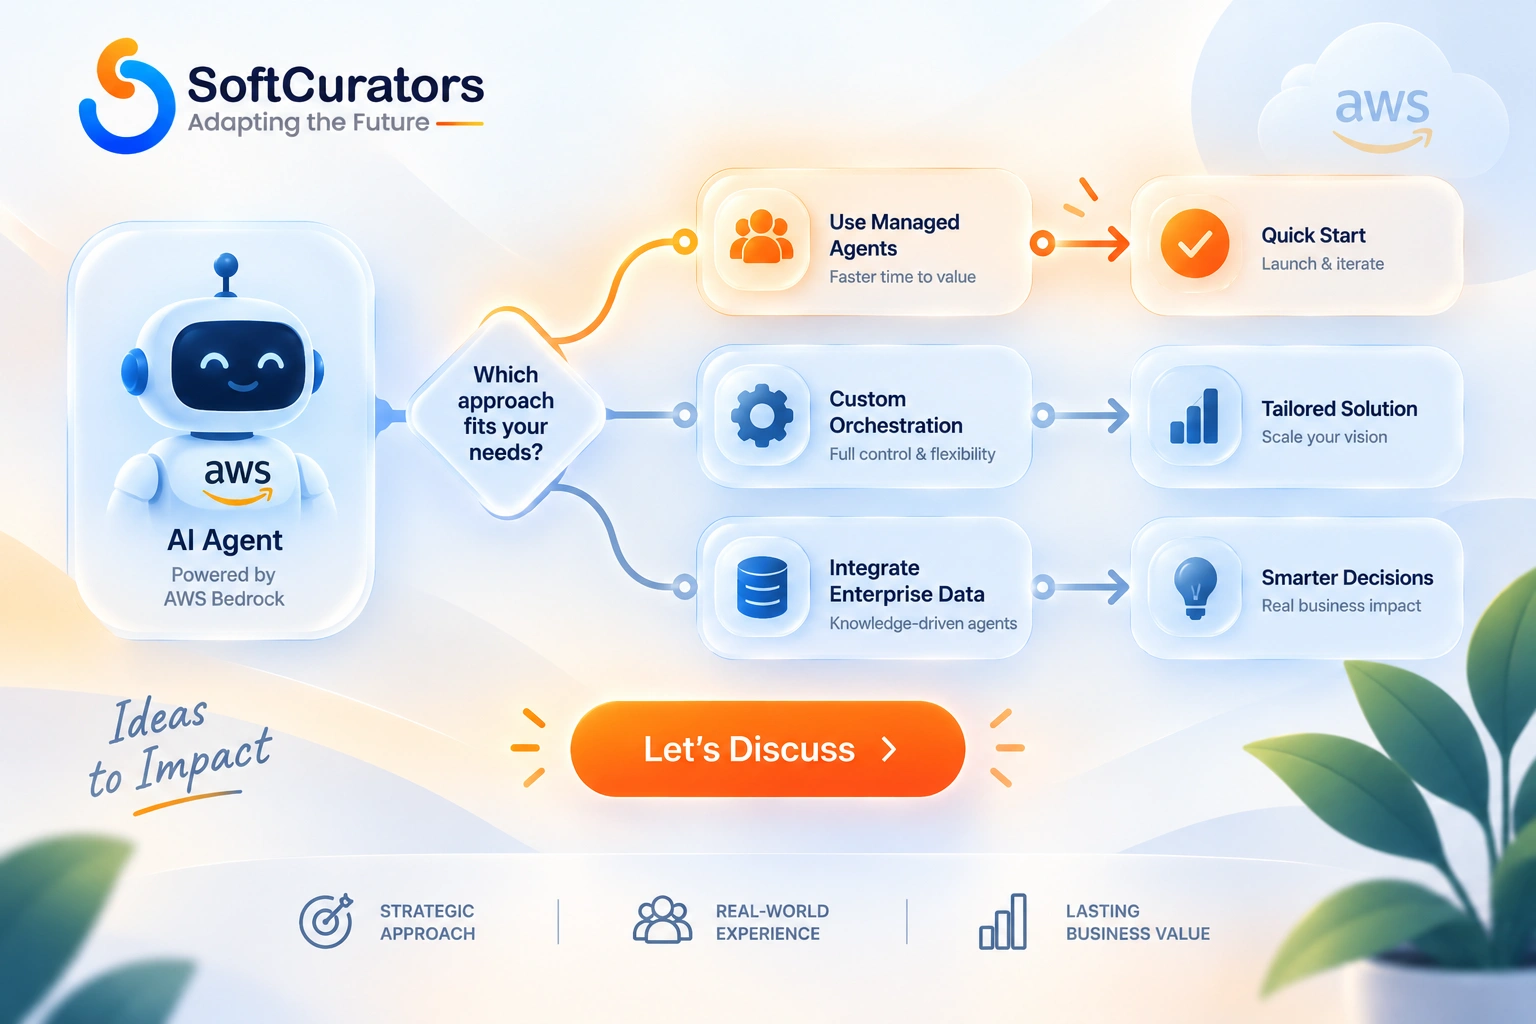
Our default recommendation: start with managed Agents for Bedrock. Here’s the reasoning, stated plainly rather than hedged.
Managed Agents give you tool selection, multi-step reasoning, and session management without writing and maintaining that orchestration logic yourself, and they inherit IAM-based access control automatically. Custom orchestration means you’re rebuilding a meaningful piece of what Bedrock already provides, and you should only take on that rebuild when you have a specific, concrete reason the managed service can’t do what you need -not as a default starting position.
Choose custom orchestration when:
- Your agent’s control flow requires branching logic that genuinely doesn’t fit the action-group pattern -conditional multi-agent handoffs with business logic Bedrock’s orchestration doesn’t expose configuration for.
- You need tighter control over exactly how much of the reasoning trace is visible or loggable than the managed service currently exposes.
- You’re integrating with a non-AWS orchestration framework already standardized across your organization, and introducing a second orchestration pattern creates more operational complexity than it saves.
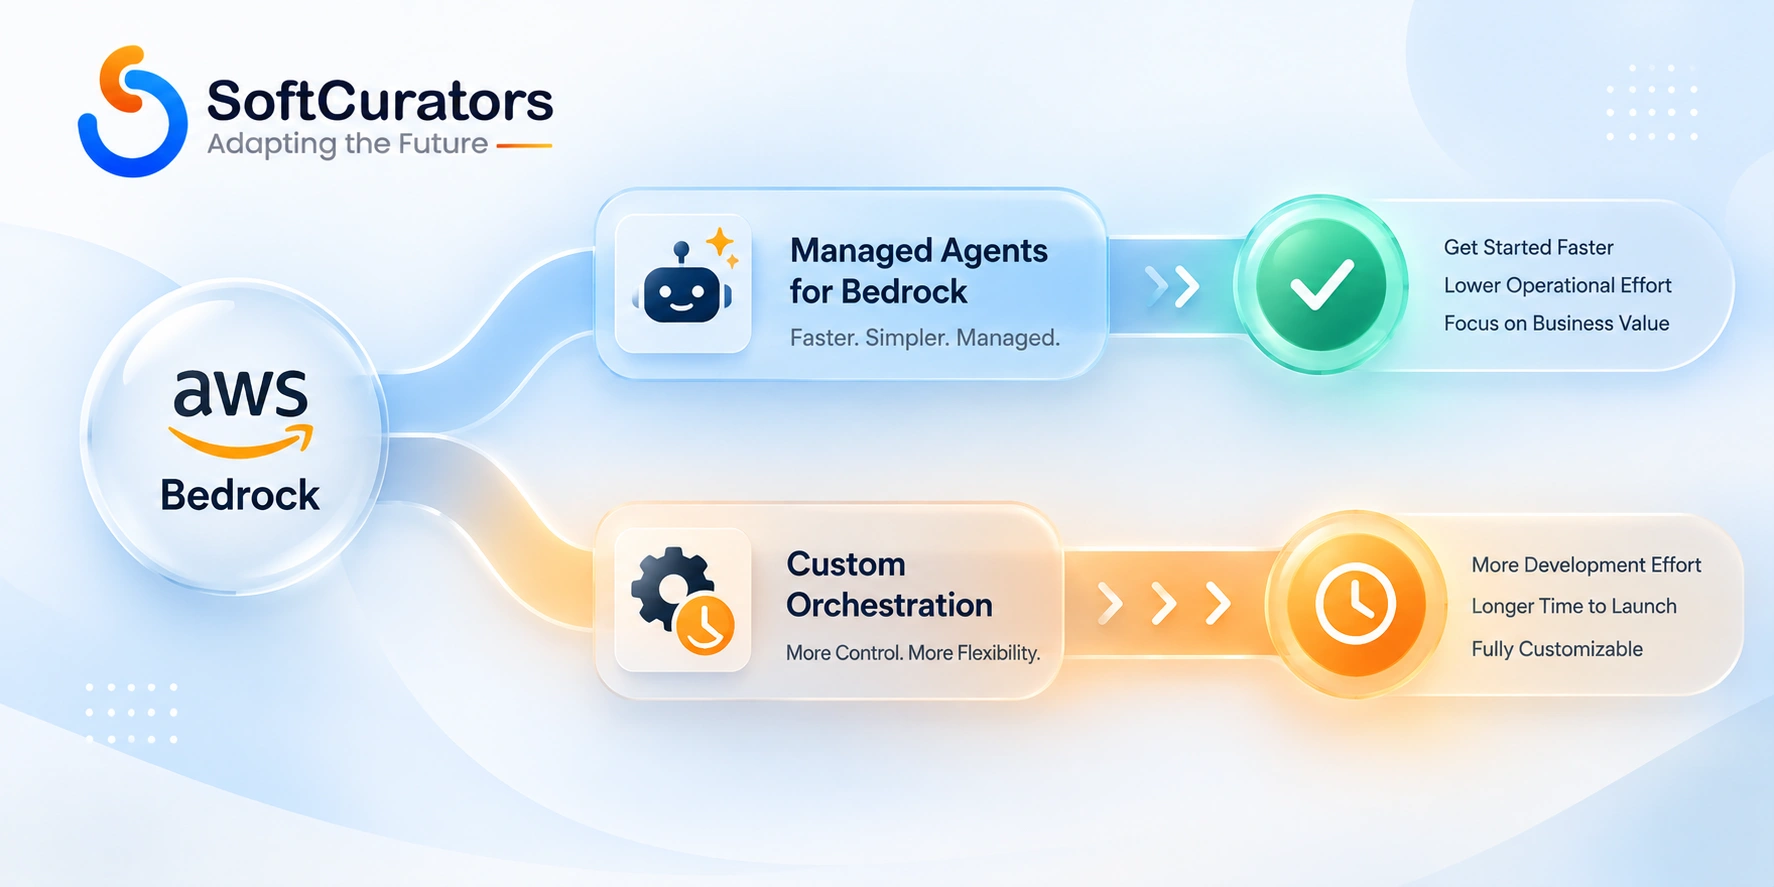
Choose managed Agents for Bedrock when:
- Your use case fits the action-group and knowledge-base pattern -most enterprise assistant, support, and internal-tool agents do.
- You want IAM-integrated access control without building an equivalent system yourself.
- Your team’s priority is reaching a working, governed agent quickly rather than maximizing control over orchestration internals, which is the more common priority for a first production agent.
Cost implications: Managed Agents don’t carry a separate orchestration fee beyond the underlying model invocation and Lambda execution costs covered later in this guide -you’re paying for the AI and compute you’d need either way. Custom orchestration adds the ongoing engineering cost of maintaining orchestration logic yourself, which is a real, recurring cost even though it doesn’t appear as a line item on an AWS bill.
Maintenance implications:
Managed Agents benefit from AWS’s ongoing feature development -new capabilities become available through configuration rather than requiring you to build them. Custom orchestration puts the entire maintenance burden, including keeping pace with new model capabilities, on your own team indefinitely.
Scalability implications: Both approaches scale on the same underlying AWS infrastructure. The practical difference is engineering scalability -a managed Agents approach lets a smaller team support more agents, since orchestration logic isn’t something they’re independently building and debugging for each one.
Risk factors: Managed Agents carry a dependency on AWS’s roadmap and configuration options -if a use case genuinely doesn’t fit the pattern, you’re constrained until AWS adds support or you migrate to custom orchestration. Custom orchestration carries execution risk: the security and reliability equivalent of what Bedrock provides by default now depends entirely on your own team building it correctly.
Time-to-market impact: Managed Agents reach a working, IAM-governed prototype meaningfully faster, since orchestration and access control come configured rather than built. Custom orchestration adds real weeks to months of additional engineering before you have equivalent functionality, let alone equivalent governance.
Comparison Table: Managed Agents for Bedrock vs. Custom Orchestration
| Factor | Managed Agents for Bedrock | Custom Orchestration on Bedrock Models |
| Time to working prototype | Days to a few weeks | Weeks to a couple months |
| Access control | Inherits IAM automatically | Must be built and maintained separately |
| Orchestration maintenance | AWS-maintained, configuration-based | Your team’s ongoing responsibility |
| Control flow flexibility | Fits most standard agent patterns | Full control, at full engineering cost |
| Best fit | Standard enterprise assistant and tool-use agents | Highly specific control flow the managed pattern can’t express |
Note: Verify current Bedrock Agents capabilities directly against AWS documentation before finalizing this decision -supported patterns expand over time.
What to Monitor Beyond Standard Application Health
Standard uptime and error-rate monitoring tells you whether the agent is running, not whether it’s behaving well. Track tool-selection accuracy against your evaluation set on a recurring basis, escalation-to-human rate as a signal of where the agent is hitting its limits, and Guardrails trigger frequency to spot emerging misuse patterns or legitimate requests being incorrectly blocked.
Risk Alert: A rising escalation rate isn’t automatically a problem -it can mean your Guardrails and human-approval design are working as intended for genuinely ambiguous requests. Investigate the specific pattern before assuming it’s either a failure or a success; the trend alone doesn’t tell you which.
How Does Bedrock Compare to Building Agents on Other Cloud Platforms?
Azure AI Foundry and Google’s Vertex AI offer broadly comparable managed agent capabilities -foundation model access, orchestration, retrieval, and safety controls -on their respective platforms. The real decision for most enterprise teams isn’t which platform has marginally better agent features; it’s which platform your organization is already running on.
Platform Choice Should Follow Your Existing Infrastructure, Not the Other Way Around
If your organization runs primarily on AWS -existing IAM structure, existing Lambda usage, existing data in AWS-native stores -Bedrock’s integration advantages compound with infrastructure you already have. The same reasoning applies in reverse for an organization built primarily on Azure or Google Cloud. Choosing an agent platform independent of your existing cloud footprint, purely on a feature comparison, tends to create integration friction that outweighs whatever marginal capability advantage motivated the choice.
When a Multi-Cloud Approach Makes Sense
Expert Recommendation: A genuinely multi-cloud organization, or one with a specific regulatory reason to keep certain workloads on a particular provider, is the real exception where evaluating agent platforms independent of a single existing footprint makes sense. For most single-cloud enterprises, this guide’s core recommendation holds regardless of provider: use the managed agent service native to your existing cloud platform by default, and justify a custom or cross-platform approach only with a specific, concrete reason, documented and revisited as your infrastructure evolves.
When Do You Need Multiple Agents Instead of One?
A single agent handles a single, coherent scope of responsibility well. Once a use case spans genuinely distinct domains -say, an internal assistant that needs to handle both HR policy questions and IT ticket creation -a multi-agent architecture, with a coordinating orchestrator agent delegating to specialized sub-agents, is usually a better fit than one agent trying to do everything.
Why Splitting Responsibility Improves Reliability, Not Just Organization
A narrowly scoped agent with a focused set of action groups is easier to test, easier to debug when it makes a wrong tool choice, and easier to reason about from a security standpoint, since its IAM permissions can be scoped tightly to exactly what its narrow responsibility requires. A single sprawling agent with access to every action group in your organization is both a worse engineering pattern and a larger security surface than the task actually requires.
Risk Alert: Multi-agent systems compound failure probability across steps, the same way any multi-step agentic process does -if each handoff between agents has a small chance of misrouting, a request passing through several agents carries a real, non-trivial chance of ending up handled incorrectly. Add explicit fallback and human-escalation paths at every handoff point in a multi-agent design, not just at the final response.
Expert Recommendation: Start with a single, narrowly scoped agent for your first production use case, even if you eventually plan a multi-agent system. Validating that one agent works reliably against real usage teaches you more about your actual failure patterns than designing a multi-agent architecture upfront on assumptions you haven’t tested yet.
Guardrails: What Enterprise Safety Controls on Bedrock Actually Cover
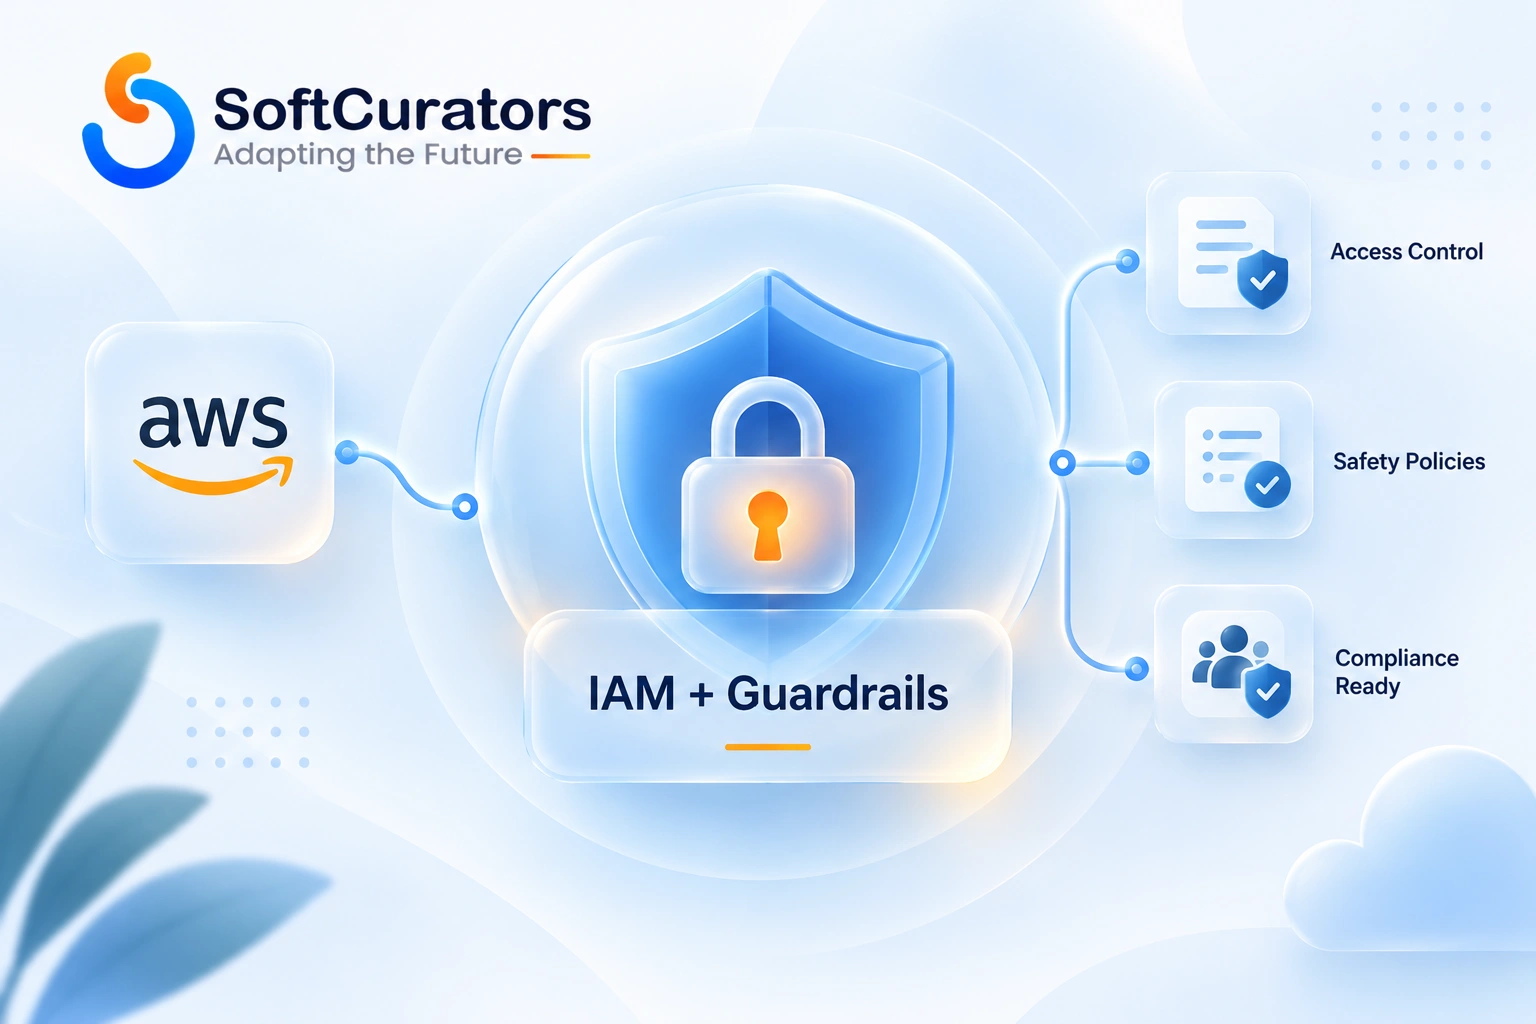
Bedrock Guardrails let you configure content filtering, denied topics, and sensitive information handling rules that apply consistently across your agents, rather than relying on prompt instructions alone to enforce boundaries a determined or careless user can potentially work around.
Why Guardrails Matter More Than Prompt Instructions Alone
A system prompt telling a model “don’t discuss competitor pricing” is a request the model generally follows, not a hard boundary -a sufficiently creative or adversarial input can sometimes get around prompt-only instructions. Guardrails apply as a separate, configurable filtering layer, giving you an enforcement mechanism that doesn’t depend entirely on the model correctly interpreting and prioritizing your instructions every single time.
Reviewing AWS’s documentation on Bedrock Guardrails directly covers the current configurable categories -denied topics, content filters, sensitive information handling -in more depth than a summary can reliably capture, since these are actively expanded.
Common Mistake: Treating Guardrails as a launch-time configuration set once and never revisited. As your agent’s real usage patterns emerge -including attempted misuse you didn’t anticipate during design -Guardrails configuration should be revisited on the same recurring cadence as the rest of your agent’s evaluation, not left as a static initial setting.
What Security and Governance Does an Enterprise Deployment Actually Require?
Beyond Guardrails, enterprise deployment of an agent introduces governance requirements general AI security guidance doesn’t fully cover, particularly around what the agent is allowed to do, not just what it’s allowed to say.
Scope IAM Roles to the Narrowest Permission Set That Works
Every action group’s underlying Lambda function should run with an IAM role scoped to exactly the permissions that specific function needs, not a broad role reused across your agent’s entire action set. This is standard least-privilege practice, but it’s easy to skip under time pressure by reusing one convenient role everywhere -a shortcut that turns a single compromised or misused action group into access to everything the agent can touch, rather than just the one function that was actually needed.
Prompt Injection Is a Real Risk for Any Tool-Using Agent
An agent that processes untrusted input -a user message, a document, data retrieved from an external source -is exposed to prompt injection, where crafted input attempts to make the agent take an action it shouldn’t. The OWASP Top 10 for Large Language Model Applications documents this and related risks, and it’s especially relevant for agents specifically, since a successful injection against an agent doesn’t just produce a bad text response -it can trigger a real action through an action group.
Governance as an Ongoing Practice, Not a Launch Checklist
The NIST AI Risk Management Framework offers a useful structure for treating agent risk as continuously managed rather than a one-time pre-launch review. Our overview of mobile app security and compliance and security and compliance for digital lending platforms cover what this discipline looks like in adjacent, regulated contexts.
Risk Alert: For agents that can take consequential actions -modifying records, sending communications, approving transactions -add an explicit human-approval step for high-impact actions rather than allowing full autonomous execution by default. This is a design decision independent of Bedrock’s specific capabilities, and it’s the single most effective control against a confidently wrong agent doing real damage.
How Should You Design for Agent Latency in a Real Product?
A multi-step agent task involves several sequential model calls and tool invocations, which adds up to meaningfully more latency than a single model response -a real user experience consideration that’s easy to overlook until users are staring at a spinner during a multi-step reasoning process.
Show Progress, Not Just a Loading Indicator
Business Perspective: Surfacing what the agent is currently doing -“checking your account,” “looking up the policy” -during a multi-step task meaningfully improves perceived responsiveness compared to a generic loading spinner, even when the total wait time is identical. This is a product design decision layered on top of the technical architecture, and it’s worth the relatively small implementation effort.
Decide Where Synchronous Response Genuinely Matters
Not every agent interaction needs to complete synchronously while a user waits. For longer-running tasks -generating a detailed report, processing a batch request -consider an asynchronous pattern where the agent works in the background and notifies the user on completion, rather than forcing a real-time wait for a task that doesn’t require one.
Common Mistake: Building every agent interaction as a synchronous, real-time exchange by default, without evaluating whether the specific task actually benefits from an immediate response versus a background-and-notify pattern. This is the same latency-budget thinking that applies to any AI feature, and it applies just as directly to agents, only compounded across multiple steps.
What Does Running Enterprise Bedrock Agents Actually Cost?
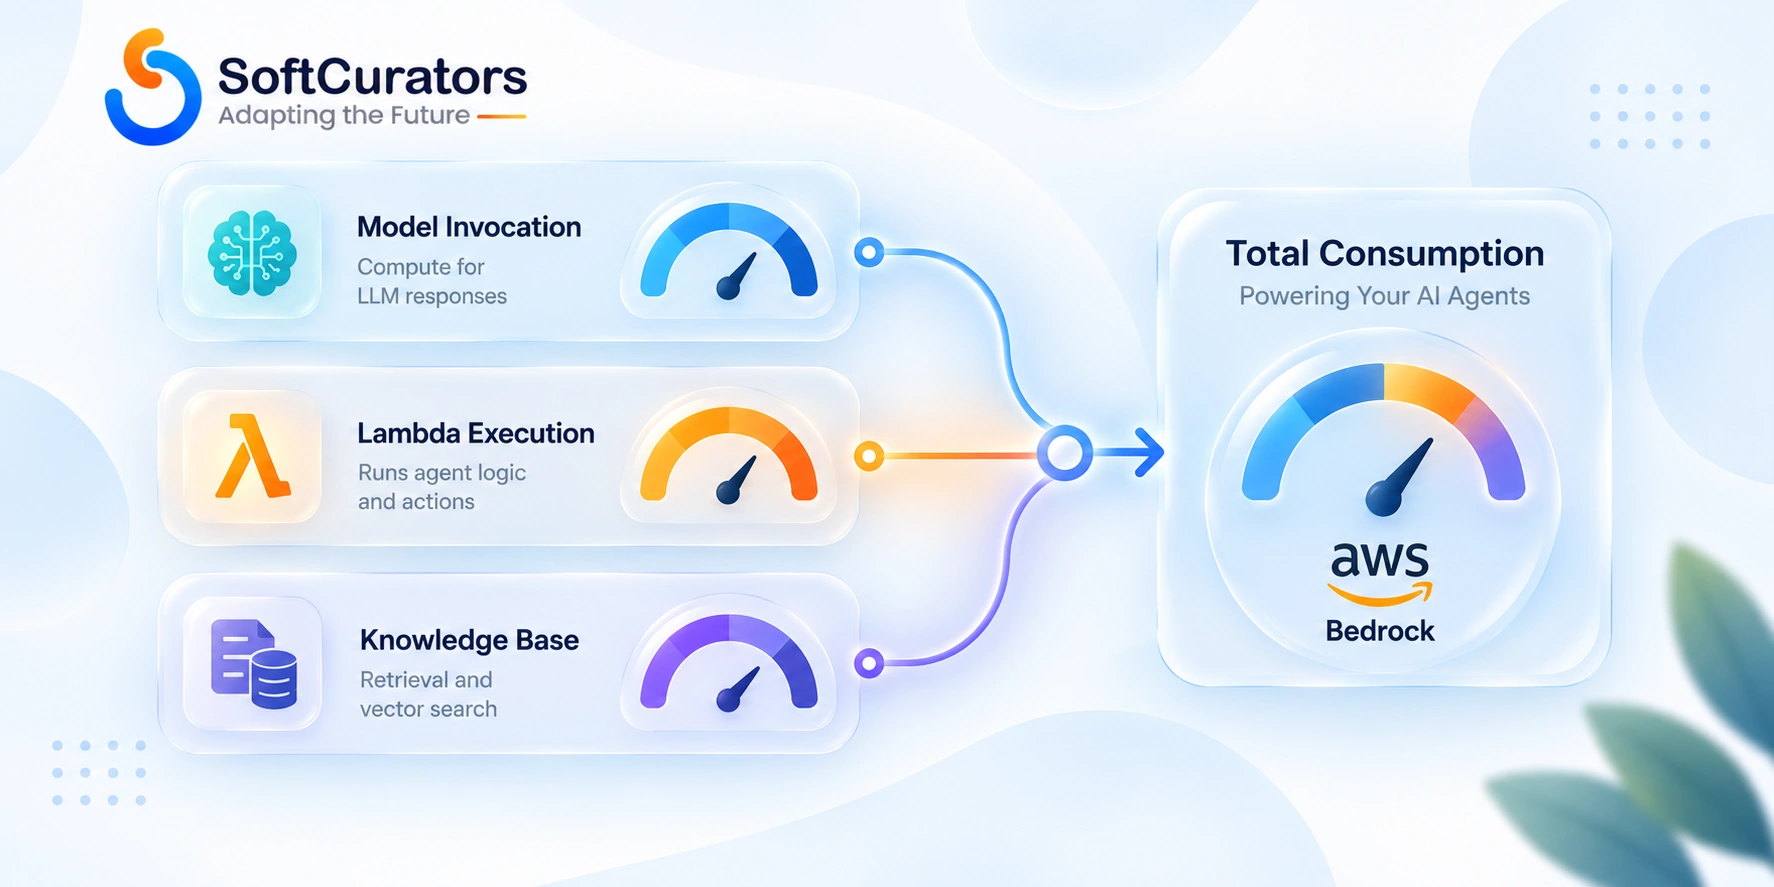
Bedrock agent cost isn’t one number -it’s the sum of model invocation cost, Lambda execution cost for your action groups, Knowledge Base storage and query cost, and Guardrails evaluation cost, each billed separately and each scaling with a different usage pattern.
Model Invocation: The Cost Most People Expect
Foundation model access through Bedrock is priced per token processed, the same underlying mechanism covered in our how to build an AI-powered app guide -driven by how much text moves through the model, not by an abstract complexity rating. An agent’s multi-step reasoning means a single user request can trigger several model invocations, not one, since each reasoning step and tool-selection decision is itself a model call.
Lambda Execution: The Cost Agent Guides Often Skip
Every action group invocation runs a Lambda function, billed by execution time and memory allocated -usually small per-call, but multiplied across every tool call an agent makes during a multi-step task, and worth modeling explicitly rather than assuming it’s negligible without checking.
Knowledge Base Costs: Storage Plus Query Volume
Knowledge Bases carry vector store costs (OpenSearch or Aurora, priced by the underlying AWS service) plus embedding generation cost each time your data syncs. High-frequency sync against large datasets is a genuine cost driver worth weighing against how much data freshness your use case actually requires, as covered earlier in this guide.
Reviewing AWS’s current Bedrock pricing directly, alongside general AWS pricing for the supporting Lambda and vector store components, gives a realistic full picture -a Bedrock-specific price alone misses the supporting infrastructure cost that comes with a real agent deployment.
Risk Alert: Set AWS Budgets alerts scoped to your Bedrock, Lambda, and OpenSearch usage before launch, not after the first unexpected bill. A popular agent making several model calls per interaction across a growing user base can scale cost faster than a team modeling only the per-request price expects.
Practical Ways to Reduce Cost Without Sacrificing Reliability
Route different reasoning steps to different models where Bedrock’s multi-provider access makes this practical -a smaller, cheaper model can often handle simple tool-selection decisions, reserving a more capable and more expensive model for the steps that genuinely require deeper reasoning. This mirrors the same model-tiering optimization that applies to any multi-step AI workflow, and it’s worth implementing once an agent is proven, not necessarily in a first version.
Caching repeated Knowledge Base queries and setting sensible limits on how many reasoning steps an agent can take before requiring human escalation both reduce cost directly -an agent stuck in an unproductive reasoning loop isn’t just a reliability problem, it’s also a cost problem, since every additional step is a billed model invocation.
How Do You Test and Evaluate an Agent Before Production?
Testing a single-turn AI feature means checking whether a given input produces acceptable output. Testing an agent means checking whether an entire multi-step trace -which tool it chose, what parameters it passed, how it interpreted the result, what it did next -was correct at every step, not just whether the final answer looked reasonable.
Build an Evaluation Set of Full Traces, Not Just Final Outputs
Assemble representative tasks your agent needs to handle, including deliberately ambiguous and edge-case requests, and define what a correct trace looks like for each -not just the final response, but the sequence of tool calls that should lead to it. An agent that reaches a coincidentally correct final answer through the wrong reasoning path is a reliability risk that final-answer-only testing won’t catch.
Test Tool Selection Specifically
Operational Perspective: A meaningful share of agent failures come from calling the wrong action group, or the right one with wrong parameters, not from the underlying model reasoning being unsound. Test tool selection as its own category, separate from overall task success, so you can tell whether a failure traces back to your action group descriptions or to the agent’s broader reasoning.
Our overview of mobile app testing, deployment, and maintenance covers the broader QA discipline this agent-specific evaluation practice sits alongside.
What Team Do You Actually Need to Build This?
Our view: a team that already knows your internal systems and can write Lambda functions is better positioned to build a first Bedrock agent than a team hired specifically for AI expertise but unfamiliar with what the agent actually needs to connect to.
Backend Engineers Own Most of the Real Work
Writing action group Lambda functions, designing IAM roles, and integrating Knowledge Base data sources are standard AWS backend engineering tasks -the Bedrock-specific learning curve is real but modest for a team already comfortable with Lambda, IAM, and API design. The harder part is usually understanding your own internal systems well enough to expose them safely, which existing team members already have a head start on.
When Specialized Expertise Genuinely Helps
Someone with hands-on Bedrock experience specifically -not general ML background -adds the most value early, around action group description quality, evaluation set design, and IAM scoping decisions, since these are the areas where Bedrock-specific patterns diverge most from general software engineering practice. This expertise pays for itself fastest during the first agent’s design phase, less so on repeat projects once your team has internalized the patterns.
Business Insight: A short, focused engagement with Bedrock-specific expertise for your first agent’s architecture and IAM design, followed by an in-house build using that foundation, is often more cost-effective than either a fully outside build or a first attempt without any Bedrock-specific guidance at all.
Common Mistakes When Building Enterprise Agents on Bedrock
- Defaulting to custom orchestration without a specific reason the managed service can’t handle. This rebuilds functionality Bedrock already provides, at real ongoing engineering cost.
- Reusing one broad IAM role across every action group. This turns a single compromised function into access to everything the agent can touch, rather than just what was actually needed.
- Writing vague action group function descriptions. This directly causes unreliable tool selection, and it deserves the same iterative testing as any other prompt in the system.
- Treating Guardrails as a one-time launch configuration. Real usage reveals misuse patterns worth configuring against on an ongoing basis, not just at initial setup.
- Building one broad agent instead of scoped, specialized agents. A single agent with access to everything is both harder to test and a larger security surface than the task requires.
- Allowing full autonomous execution for consequential actions. High-impact actions need an explicit human-approval step, not full autonomy by default.
- Testing only final answers, not full reasoning traces. An agent can reach a coincidentally correct answer through unreliable reasoning that final-answer testing won’t catch.
- Modeling cost from model invocation alone. Lambda execution and Knowledge Base costs are real, separate line items that scale with agent usage.
- Rolling out a new agent version to all production traffic at once. Aliases exist specifically to let you test against a draft version before committing full traffic to a change.
- Forcing every agent interaction into a synchronous, real-time wait. Longer tasks often benefit from an asynchronous, notify-on-completion pattern instead.
What Do Real Enterprise Agent Use Cases Look Like?
The architecture principles in this guide apply across industries, but the specific action groups, data sources, and compliance requirements shift by domain. Our vertical-specific AI coverage applies these same underlying patterns to real feature sets.
- AI in loan lending and AI in credit scoring, where an agent’s action groups often touch regulated financial decisions, making the human-approval design point above especially relevant.
- AI in real estate mobile apps, where a Knowledge Base grounding an agent in property data faces similar sync-frequency and data-quality considerations to those covered earlier in this guide.
- Our overview of the top AI tools for businesses, useful context for how Bedrock-based agents fit alongside the broader AI tooling landscape enterprises are evaluating.
If you’re specifically weighing what an AI feature costs to add to an existing enterprise system rather than build fresh, our AI integration costs guide covers the total-cost-of-ownership framework -scoping, engineering, data readiness, and more -that applies alongside the Bedrock-specific costs covered in this guide.
Where Is Enterprise Agent Development on AWS Headed Next?
The following are directional trends based on current momentum, not settled fact -verify against current AWS documentation before treating any of these as a firm planning assumption.
- Expanding multi-agent collaboration support within Bedrock’s managed offering, likely narrowing the cases where custom orchestration is genuinely necessary over time.
- Growing enterprise expectation of built-in audit trails for agent actions, particularly in regulated industries, likely increasing demand for Bedrock’s native IAM and logging integration over custom-built alternatives.
- More granular Guardrails configuration, likely reducing reliance on prompt-only behavioral controls as the primary safety mechanism.
- Continued model provider expansion within Bedrock, strengthening the case for Bedrock’s unified access layer as an alternative to integrating providers individually.
Final Summary and Next Steps
Building enterprise AI agents on AWS Bedrock comes down to a small number of deliberate decisions: default to managed Agents for Bedrock over custom orchestration unless you have a specific reason otherwise, scope IAM permissions narrowly per action group rather than broadly across an entire agent, treat Guardrails and human-approval steps as ongoing governance rather than launch-time checkboxes, and evaluate full reasoning traces, not just final answers, before calling an agent production-ready.
The teams that get this right treat Bedrock’s managed services as the default they deviate from only with a concrete reason, not a starting menu of equally valid options. They scope their first agent narrowly, validate it against real usage, and expand into multi-agent architectures and broader capability only once that first agent has proven the pattern actually holds up.
Consultant’s Tip: Before your next architecture review, map your planned agent’s action groups against the IAM permissions each one actually needs, and check whether any of them currently share a broader role than necessary. That single audit surfaces more real security risk than most initial Bedrock agent designs account for.
Risk Alert: Bedrock’s feature set and pricing continue to evolve, and a design decision that’s correct today may be worth revisiting as AWS expands managed Agents’ supported patterns. Treat this guide’s architecture reasoning as durable, but verify specific capabilities and current pricing against AWS’s own documentation before finalizing any production plan.
Next Step
If you’re planning an enterprise agent deployment on AWS Bedrock and want a second set of eyes on the architecture before you build, an Architecture Review with Softcurators is a direct way to work through your action group design, IAM scoping, and managed-versus-custom orchestration decision before committing engineering time. Softcurators works across AI development, AI consulting services, and AI automation. You can review our AI app development solutions page, browse our broader services overview, or get in touch directly to talk through your specific agent architecture.
Frequently Asked Questions
Should I use managed Agents for Bedrock or build my own orchestration?
Start with managed Agents for Bedrock unless you have a specific, concrete reason your control flow doesn't fit the action-group pattern. Custom orchestration rebuilds functionality Bedrock already provides, at real ongoing engineering cost most teams don't need to take on.
Do I need my organization to already be on AWS to use Bedrock for agents?
Not strictly, but it's the strongest case for choosing Bedrock specifically. If you're not already invested in AWS, adopting the platform solely to build one agent is usually disproportionate -a foundation model provider's API directly, on your existing infrastructure, is a more proportionate starting point.
How does Bedrock handle connecting an agent to our internal systems?
Through action groups, each backed by an AWS Lambda function you write, with a schema describing what it does. The agent selects and calls the appropriate function based on the user's request and the conversation context.
What's a Knowledge Base in Bedrock, and do I need one?
A Knowledge Base is Bedrock's managed retrieval-augmented generation (RAG) capability, connecting your agent to your own data. You need one if your agent should answer based on your specific enterprise information rather than only the model's general training knowledge.
How much does it cost to run an agent on Bedrock at enterprise scale?
It's the sum of model invocation cost (which scales with how many reasoning steps a task requires, not just one call per request), Lambda execution cost for action groups, and Knowledge Base storage and sync cost -not a single number, and worth modeling across all three before committing to a budget.
What are Bedrock Guardrails, and are they necessary?
Guardrails are configurable content filtering and safety controls that apply consistently across your agents, independent of prompt instructions alone. They're worth using for any enterprise deployment, since prompt-only instructions can potentially be worked around by adversarial or unusual input.
Is prompt injection a real concern for agents specifically, or just chatbots?
It's arguably a bigger concern for agents, since a successful injection doesn't just produce a bad text response -it can trigger a real action through an action group, making the consequences of a successful attack more serious than with a text-only feature.
When should I build multiple specialized agents instead of one broad agent?
Once a use case spans genuinely distinct domains -different data sources, different action groups, different user intents -a multi-agent architecture with a coordinating orchestrator is usually more reliable and easier to secure than one agent handling everything.
How do I test an AI agent before putting it into production?
Build an evaluation set of full reasoning traces, not just final outputs -define what correct tool selection and reasoning looks like for representative and edge-case tasks, and test tool selection specifically as its own category separate from overall task success.
Should an agent be allowed to take actions autonomously, or does every action need human approval?
It depends on the action's consequence. High-impact actions -modifying records, sending communications, approving transactions -should have an explicit human-approval step. Lower-stakes, easily reversible actions can reasonably run autonomously.
What IAM setup does a Bedrock agent need?
Each action group's underlying Lambda function should run with an IAM role scoped to exactly the permissions that specific function needs, following least-privilege practice, rather than one broad role reused across every function the agent can call.
How often should Knowledge Base data sync?
Match sync frequency to how often your underlying data actually changes, not to a default setting -frequent syncing against rapidly changing data costs more in both compute and operational overhead than the same frequency applied to slower-changing reference material.
Can I use models from providers other than Amazon through Bedrock?
Yes, Bedrock provides access to models from multiple providers through one consistent API, which is one of its genuine advantages over integrating each provider's API separately if you expect to compare or switch models over your agent's lifetime.
What's the biggest hidden cost in a Bedrock agent deployment?
Lambda execution cost across action group calls and Knowledge Base sync cost are both commonly underestimated relative to model invocation cost, which is usually the number teams model first and the other two the numbers they forget.
How is agent evaluation different from testing a standard AI feature?
Standard AI feature testing checks whether an input produces acceptable output. Agent evaluation needs to check the full reasoning trace -which tools were selected, with what parameters, and why -since a coincidentally correct final answer can still reflect unreliable underlying reasoning.
Do I need a dedicated ML team to build agents on Bedrock?
Not necessarily. Product and backend engineers who understand your existing systems and can write Lambda functions for action groups can build most Bedrock agent integrations without specialized ML expertise, since Bedrock's managed services handle much of the AI-specific complexity.
What happens if my agent's use case genuinely doesn't fit Bedrock's managed Agents pattern?
That's the specific, concrete condition under which custom orchestration on Bedrock's foundation models directly becomes the right call -but it should be a deliberate decision based on a real limitation you've hit, not a default starting position.
How does multi-agent architecture affect reliability?
It can improve reliability through narrower, more testable scope per agent, but it also compounds failure probability across handoffs between agents. Explicit fallback and human-escalation paths at every handoff point are essential in a multi-agent design.
Should regulated industries approach Bedrock agent development differently?
Yes. Regulated industries -financial services, healthcare -should treat human-approval requirements for consequential actions, IAM scoping, and audit logging as non-negotiable design requirements from the start, not features to add later if time allows.
Can Bedrock agents access data outside of AWS?
Action groups can call any Lambda function you write, and that function can call external systems and APIs outside AWS, provided appropriate network and authentication configuration is in place. Bedrock itself doesn't restrict an agent to AWS-only data sources.
What's the realistic timeline to launch a first production agent on Bedrock?
Using managed Agents for Bedrock with a narrowly scoped first use case, a working prototype is commonly achievable in days to a few weeks, though enterprise-grade IAM configuration, Guardrails tuning, and evaluation testing extend that before a genuinely production-ready launch.
Does Bedrock lock us into AWS long-term?
Using Bedrock's managed Agents specifically does create AWS-specific dependency in your orchestration layer, though the underlying foundation model access is comparatively portable. This is worth weighing explicitly if platform independence is a strategic priority for your organization.
How do we monitor an agent's behavior after it's live?
Beyond standard application monitoring, track tool selection accuracy, escalation rates to human review, and Guardrails trigger frequency on a recurring basis -these agent-specific signals reveal problems that general uptime and error-rate monitoring won't surface.
What's a reasonable first Bedrock agent project for a team new to this?
A narrowly scoped internal tool -an agent that answers questions against a single Knowledge Base and calls one or two well-defined action groups -validates the architecture pattern with contained risk before expanding into broader or more consequential use cases.
How does session memory work across multiple conversations with the same user?
Bedrock's session memory covers a single conversation, not a user's history across separate sessions. Persisting and retrieving context across sessions requires your own data store, commonly accessed through a Knowledge Base or dedicated action group, not automatic behavior from session handling alone.
Should we test a new agent version against all production traffic immediately?
No. Use aliases to point a draft version at test traffic while production continues on a stable, known-good version, then roll out gradually while monitoring tool-selection accuracy and escalation rates -an evaluation set alone rarely catches everything real usage will surface.
Does agent latency matter more than latency for a single model call?
Yes, since a multi-step agent task involves several sequential model calls and tool invocations, compounding total wait time. Surfacing progress during multi-step reasoning, and considering an asynchronous pattern for longer tasks, both meaningfully improve the real user experience.
Do we need a dedicated AI engineering hire to build our first Bedrock agent?
Not necessarily as a permanent hire. Existing backend engineers familiar with Lambda, IAM, and your internal systems can build most of the work; short-term Bedrock-specific expertise adds the most value during the first agent's architecture and IAM design phase specifically.
How should an evaluation set evolve after an agent goes live?
It should keep growing to include real production examples that surfaced problems, not remain frozen at its original test cases. An evaluation set that never updates stops reflecting the agent's actual failure modes as real usage patterns emerge over time.
Should we choose Bedrock over Azure AI Foundry or Google Vertex AI for our agent?
This should follow your existing cloud infrastructure, not a standalone feature comparison. If your organization already runs primarily on AWS, Bedrock's IAM and infrastructure integration advantages compound with what you have; the same logic applies to choosing Azure or Google Cloud's equivalent if that's your existing footprint.
Can we reduce Bedrock agent costs without hurting reliability?
Yes -routing simpler reasoning steps to smaller, cheaper models while reserving capable models for steps that need deeper reasoning, caching repeated Knowledge Base queries, and capping reasoning steps before requiring human escalation all reduce cost without compromising the agent's core reliability.
What happens if an agent gets stuck in a reasoning loop?
Beyond being a reliability problem, this is a direct cost problem, since every additional reasoning step is a billed model invocation. Setting a sensible limit on reasoning steps before requiring human escalation protects against both runaway cost and a genuinely stuck agent.
Is a multi-cloud agent strategy ever the right approach?
For a genuinely multi-cloud organization or one with a specific regulatory reason to keep certain workloads on a particular provider, yes. For most single-cloud enterprises, using the managed agent service native to your existing platform is the more practical default.
What should we monitor for a Bedrock agent beyond standard uptime?
Tool-selection accuracy against your evaluation set, escalation-to-human rate, and Guardrails trigger frequency all reveal problems standard application health monitoring won't surface, since they measure agent behavior quality, not just whether the system is running.
Does a rising escalation rate mean something is wrong with the agent?
Not necessarily -it can indicate Guardrails and human-approval design working correctly for genuinely ambiguous requests. Investigate the specific pattern behind the trend rather than assuming a rising number is automatically a failure.
How do we know if our first Bedrock agent is ready to expand into a multi-agent system?
Once the first agent has proven reliable against real usage and its scope has genuinely outgrown a single agent's coherent responsibility -not before, and not based on an upfront assumption that multi-agent is the eventual goal regardless of what the first agent's real-world performance shows.
Does Bedrock pricing or feature availability change often enough to affect planning?
Yes, meaningfully enough that this guide's architecture reasoning is built to stay durable while specific capabilities and pricing should be re-verified against AWS's own documentation before finalizing a production plan. Treat published pricing figures as a starting reference, not a permanent number.
What's the difference between an agent alias and an agent version in Bedrock?
A version is a specific, fixed configuration of an agent; an alias is a named pointer you can move between versions, letting you route test traffic to a draft version while production traffic continues hitting a stable version, without changing any application code that references the alias.
Should smaller companies without a dedicated cloud team consider Bedrock agents at all?
If the company already runs on AWS for other workloads, yes -the IAM and infrastructure integration benefits apply regardless of team size. If AWS isn't already the company's platform, adopting it specifically for one agent project is usually a larger commitment than the use case justifies.
What's the most important architectural decision to get right before writing any code?
Whether to use managed Agents for Bedrock or custom orchestration, made deliberately with a specific reason if you deviate from the managed default -every other decision in this guide, from IAM scoping to evaluation design, follows more easily once that foundational choice is settled correctly.
